

Informatics at the service of collective well-being and personal development.
The Faculty of Informatics has a vision of a world in which the intensive and growing use of informatics is oriented towards collective well-being and personal development. Its mission is to contribute to this orientation through education, scientific research and service to society.
The studies
When you choose to study computer science, you're guaranteed immediate access to an exciting, multi-faceted career. Through a comprehensive range of courses - bachelor's, master's, specialization master's and doctorate - the Faculty of Computer Science offers you quality training based on scientific rigor and critical thinking, while emphasizing interdisciplinarity and societal responsibility.

Research
The mission of the Faculty of Computer Science is to ensure cutting-edge scientific research, open to the creation and integration of knowledge that feeds teaching, technological innovation and societal debate.

Service to society
The Faculty of Computer Science contributes to the development of our social, economic, technological and political environment by disseminating knowledge and providing advice at regional, national and international levels. Through the synergy between researchers and industry, and by making knowledge and know-how available, it participates in numerous missions of service to society.

International
The Faculty of Computer Science's international outlook is fundamental to the development of its teaching and research activities.

Organization
The Faculty of Computer Science has organized itself to manage its missions in the best possible way. It has around a hundred members at the service of teaching, research and service to society.
A word from the Dean
IT is a key to understanding, progress and responsibility in the face of the challenges and issues facing our society.
Read the article
Image

Animation
A series of events and players revolve around the Faculty of Computer Science.

Spotlight
News
Article
-
Faculty of Computer Science
NaDI Institute
A study by VUB and UNamur shows that AI agents develop their own “artificial natural language” to communicate about complex data
Artificial Intelligences (AI)
A study by VUB and UNamur shows that AI agents develop their own “artificial natural language” to communicate about complex data
Artificial Intelligences (AI)
AI systems spontaneously develop their own language, tailored to their sensors, rather than copying human language.
Researchers from the VUB’s Artificial Intelligence Lab and the University of Namur (UNamur) demonstrate, in a new large-scale study, how autonomous AI systems can spontaneously develop, without human intervention, a functional and shared language. Unlike large language models such as ChatGPT, which learn existing human language by heart, these AI agents construct their own communication system, directly rooted in their specific sensors and environment. This discovery represents a major breakthrough for communication between autonomous systems, such as self-driving cars, robots and industrial sensors.
A layer of abstraction for non-human senses
Current AI language models focus on understanding and generating human languages such as Dutch or English. These human languages are historically rooted in our own sensory perceptions. When physical or virtual AI agents are equipped with sensors for which humans have no direct sensory equivalent – such as lidar, sonar, infrared or chemical analysis – existing human language proves insufficient.
Jérôme Botoko Ekila, a PhD student at the VUB’s AI Lab, explains: ‘Instead of forcing AI systems to communicate in a human language that does not correspond to their sensors, we allow them to develop their own “artificial natural language”. They construct effective concepts that correspond exactly to what they perceive via their sensors, even if the data is incomprehensible to humans.’
As, in practice, the sensors on different machines or vehicles can never be calibrated identically, the researchers believe that this language offers the ideal solution.
Paul Van Eecke, professor of artificial intelligence at the VUB: “In industrial or physical applications, it is simply unrealistic to expect all the sensors on different robots or vehicles to be calibrated in exactly the same way. Humans solve this problem through language: if I say I am standing near the ‘red car’, we understand each other without our eyes registering exactly the same colour values. Language provides a layer of abstraction above the sensor readings, and this is precisely what we are now allowing these AI agents to construct autonomously.”
Self-organisation and evolution
Instead of pre-programmed words or fixed codes, the researchers simply provided the agents with the basic mechanisms underpinning the evolution of human language: the local invention of words, the adaptation of conceptual prototypes, and the incorporation of feedback following successful or failed communication.
Image

What’s fascinating is that there’s no central computer imposing the rules. Each time, we let two agents communicate with one another at a local level. It is solely through these individual interactions and updates that a global convention emerges spontaneously across the entire population. This principle of self-organisation allows the language to optimise itself automatically: the agents create exactly the number of categories needed to carry out their tasks efficiently, without superfluous details.
Tested on 37 datasets
The universal applicability of the method has been demonstrated across 37 varied and complex datasets. The agents successfully developed their own vocabulary to communicate, notably regarding physico-chemical analyses of wine, NASA data on exoplanets, visual datasets, and images of birds or faces. In all these situations, the agents successfully synthesised the data into new, shared concepts.
Transparent and adaptive
Transparency is a notable advantage of the systems developed. Unlike many ‘black-box’ AI models, researchers can precisely determine the meaning of a specifically developed word, as the prototype can be directly linked to the values of the underlying sensors.
Furthermore, these evolving linguistic systems are extremely robust. When the environment changes, when sensors produce noise, or when individual agents have a different structure, the language automatically adapts to the new circumstances through continuous interaction.
Reference
Botoko Ekila, J., Verheyen, L., Nevens, J., Beuls, K., & Van Eecke, P. (2026). Emergent Communication in Continuous Worlds: Self-Organization of Conceptually Grounded Vocabularies at Scale. Transactions of the Association for Computational Linguistics, vol. 14, pp. 2234–2257. DOI: 10.1162/TACL.a.799
Funding and collaboration
This research was carried out as part of a collaboration between the Artificial Intelligence Laboratory at the Vrije Universiteit Brussel (VUB) and the Faculty of Computer Science at the University of Namur (UNamur), and was funded by the Research Foundation – Flanders (FWO) and the Belgian National Research Fund (FNRS) as part of the WEAVE project.
Article
-
Faculty of Computer Science
NaDI Institute
Research from UNamur Makes Artificial Intelligence Tools More Reliable
Artificial Intelligences (AI)
Computer science (IT)
Digital transition
Research from UNamur Makes Artificial Intelligence Tools More Reliable
Artificial Intelligences (AI)
Computer science (IT)
Digital transition
Researchers at UNamur have developed a new method that has uncovered 32 previously undetected bugs in some of the most widely used software libraries for training artificial intelligence models. Originating from a master’s thesis, this research has already led to fixes in several software programs used by millions of developers around the world.
Before artificial intelligence can recognize an image, understand a text, or answer a question, it must first be trained. To do this, developers and data scientists use specialized software libraries—true “toolboxes” that enable the construction of these AI models.
A research team comprising the University of Namur, the University of Passau (Germany), and TU Delft (Netherlands) has been studying this software. Their goal: to detect bugs that are particularly difficult to spot and that could cause a program to crash suddenly.
A New Method for Detecting Hidden Bugs
To verify that these libraries are functioning properly, researchers use software capable of automatically generating thousands of tests. The purpose of these tests is to push the programs to their limits in order to identify any potential errors.
Until now, however, these tools had a major limitation: whenever a test caused a software library to malfunction, the software responsible for running the tests would also stop working. This made it impossible to pinpoint the exact source of the problem or report it to the developers.
Researchers at UNamur have therefore devised a new method. Now, each test is run separately. If one of them causes a crash, it is isolated: the testing software continues to run, logs the error, and carries on with its analysis. This makes it possible to automatically detect bugs that previously went unnoticed.
32 bugs discovered and already fixed
Using this new method, researchers analyzed 1,648 modules from the leading machine learning libraries and uncovered 32 previously unknown bugs. Several of these affected software that has become indispensable for training artificial intelligence models.
These issues were reported to the development teams. Several have already been acknowledged and fixed. “When a bug is fixed at this level, potentially thousands, or even millions, of users benefit,” notes Xavier Devroey, a professor in the Faculty of Computer Science at UNamur and a member of the PReCISE research center at the Namur Digital Institute (NaDI). Beyond these fixes, this research helps make the software on which so many artificial intelligence applications rely today more reliable.
Research that grew out of a thesis
This breakthrough originated from Lucas Berg’s master’s thesis, completed at UNamur under the supervision of Professor Xavier Devroey. As part of his research internship, Lucas Berg then joined Professor Annibale Panichella’s team at TU Delft to work on Pynguin, the open-source automated test generation tool developed at the University of Passau by Professor Gordon Fraser’s team, mentioned earlier.
Initially, his goal was to improve this tool. By preventing crashes while discovering bugs, this first contribution subsequently caught the attention of researchers at the University of Passau, who were facing the same problem, leading to an international collaboration that would result in a joint scientific publication.
Lucas Berg is currently pursuing a Ph.D. at the Faculty of Computer Science at UNamur under the supervision of Professors Wim Vanhoof and Xavier Devroey. The results of this research were presented at the IEEE International Conference on Software Testing, Verification, and Validation (ICST 2026), one of the most prestigious international conferences in the field of software testing.
This research also received support from the Wallonia Public Service (SPW Research) and Wallonia-Brussels International. This recognition underscores the quality of this work and its significance to the international scientific community.
The Namur Digital Institute (NaDI)
At NaDI, researchers develop innovative solutions to the new societal challenges posed by the digital revolution (eGov, eHealth, eServices, big data, etc.). Drawing from a variety of disciplines, the researchers combine their expertise in computer science, technology, ethics, law, management, and sociology. Comprising six research centers, the Namur Digital Institute offers unique multidisciplinary expertise in all areas of computer science, its applications, and its social impact.
Article
-
Faculty of Computer Science
AI and Quality Control: When Humans Stay in Control
Artificial Intelligences (AI)
Computer science (IT)
Medicine
AI and Quality Control: When Humans Stay in Control
Artificial Intelligences (AI)
Computer science (IT)
Medicine
How can anomaly detection on a production line be improved? It was in response to a very concrete problem encountered at the company where he works that Arnaud Bougaham, with the support of his employer, decided to devote his thesis to this topic at the UNamur School of Computer Science. The goal? To develop an artificial intelligence model that assists operators in detecting anomalies on an industrial production line by reducing false alarms and making the diagnosis easier to understand. This approach also holds promise for deployment in the medical field.
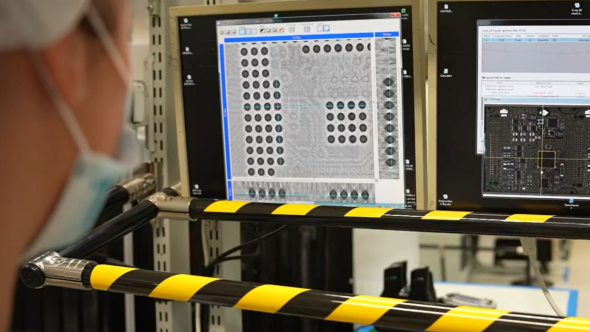
Missing components, fragile solder joints, reversed polarity, scratches, or foreign objects such as a screw that falls onto the product: on a production line for automotive electronic components, such as the one at AISIN Europe, defects—even if they are rare—must be detected immediately and accurately. “My goal was to teach a computer to distinguish between what is normal and what is abnormal in images,” explains Arnaud Bougaham, a data scientist at AISIN Europe and an associate researcher at the Faculty of Computer Science at UNamur.
On a production line, images are captured by cameras positioned above a conveyor belt, and a computer system is then tasked with verifying, at a high rate, that each part meets specifications. “However, while the traditional inspection system does its job well, it also generates a lot of false positives—false alerts. This has a significant impact on the work of the people responsible for confirming or dismissing the alerts: they are constantly called upon, at the risk of wasting time and energy.” It is this process that Arnaud Bougaham decided to improve for his company by beginning a doctoral thesis in 2020 at the HuMaLearn laboratory in the School of Computer Science—a lab recognized for its expertise in machine learning—under the supervision of Professors Benoit Frenay and Isabelle Linden.
Today, the results of his dissertation were just presented, and they look promising. “I have developed a model that, using artificial intelligence, very accurately and reliably distinguishes a normal image from one that is not, thereby reducing the false alarms of the past.”

In addition, when a defect is suspected, the model can precisely pinpoint the affected area: the operator can view the indication, manipulate the part if necessary, and then make a decision.
Another benefit of the tool? The system doesn’t just display a verdict; it also indicates the level of confidence the system has in its prediction. “The goal is to filter out simple cases and draw attention to more complex ones, so that experts are no longer overwhelmed by incorrect diagnoses and can focus on what really matters,” emphasizes Arnaud Bougaham.
Potential Beyond the Automotive Industry
While the tool was primarily designed to meet the needs of the automotive manufacturing industry, its underlying logic is generic. “It could be adapted for use in factories that manufacture hardwood flooring, wood, or fabric. But also in the medical sector,” says Arnaud Bougaham enthusiastically. “A disease is, ultimately, an anomaly in an image. The challenges are similar: when there’s a defect, it’s essential to detect it while minimizing false positives as much as possible. In the medical sector, having a similar tool that streamlines the analysis while leaving the final decision to the doctor can make a real difference.”
In this approach, AI is not an autopilot, but a decision-making tool that serves humans. “The goal is for the person to make the final decision, not for it to happen automatically,” adds Arnaud Bougaham. It is an assistant that “filters, explains, and provides all the information so that, ultimately, a person can make the decision.”

When Research Meets “Real-World Truth”
Arnaud Bougaham’s dissertation grew out of a dual role: as a doctoral student at UNamur and, at the same time, as an engineer at AISIN Europe. This position gave him access to what he calls “the reality on the ground.” “In the lab, you can get very good results, but in production, there’s a reality with a specific environment.” Noisy data, variable conditions, cost constraints, and above all, production pace: “Our system has to operate at the same pace as the production line.” By dividing his time between AISIN Europe and UNamur, Arnaud Bougaham demonstrates how a dissertation can have a tangible impact on real-world needs—all while balancing the operations and obligations of both organizations.
Image

On the academic side, we tend to focus more on in-depth analysis to find long-term solutions, whereas on the industrial side, we’re more concerned with finding a reliable solution right here and now. This is where, when working simultaneously for both sectors, we must demonstrate a willingness to compromise, engage in dialogue, and build trust. But this synergy between academic research and industrial reality allows us to achieve very fruitful results.
Roll out, expand, strengthen
Beyond the promises, this research is already being applied to real-world use cases. At AISIN Europe, the framework developed is currently being integrated into an active production line to detect unexpected components (such as a screw) on printed circuit boards. In the medical field, the approach is geared toward analyzing responsiveness in comatose patients through medical imaging that allows for the observation of organ and tissue function. Certain techniques are also being adapted for applications involving the segmentation of ovarian cancer or lymphoma.
These results also demonstrate how artificial intelligence can be reliable and human-centered in high-risk environments.
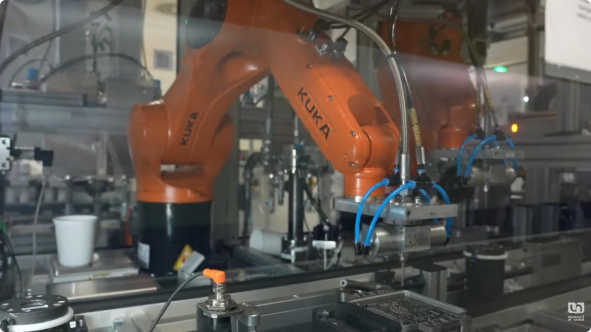
The Project in Pictures: AI Serving People in the Industrial Sector—Myth or Reality? :
This article is from the "Impact" section of Omalius magazine, Issue #41 (June 2026).

News
-
Faculty of Law
NaDI Institute
NaDI doctoral students are launching “What If AI…,” a lecture series aimed at “demystifying artificial intelligence”
Artificial Intelligences (AI)
NaDI doctoral students are launching “What If AI…,” a lecture series aimed at “demystifying artificial intelligence”
Artificial Intelligences (AI)
Through five interdisciplinary lecture-workshops, doctoral students from UNamur NaDI invite the general public to develop a critical perspective on artificial intelligence, which is already transforming our daily lives.
Artificial intelligence is now accessible to everyone. Yet, while many people use it every day, few truly understand how it works, its limitations, or the issues surrounding it. To address this need, the Namur Digital Institute (NaDI) is launching “What If AI…,” a series of lecture-workshops open to the general public, coordinated by doctoral students Elisa De Coster (PReCISE) and Aline Nardi (CRIDS).
“The idea behind the project is to demystify artificial intelligence,” begins Elisa De Coster. “As researchers, we’re fortunate to be aware of the issues raised by AI. We wanted curious members of the public to have access to these keys to understanding as well.”
“Before 2022 and the rise of ChatGPT, these tools were limited to a niche audience,” continues Aline Nardi. “Since then, the use of AI has become widespread at record speed, but reflection on the societal implications of these uses has not kept pace. This series of lectures is an invitation to take a step back and understand what’s happening behind the scenes.”
Different Perspectives for a Better Understanding of AI
Each session, lasting about two hours, will bring together the perspectives of several specialists. A doctoral student in computer science will explain the technical workings of AI, while his counterpart in law will address the legal, ethical, and societal implications.
Speakers from the professional world will share their real-world experience, and an interactive activity will allow the audience to put these concepts into practice. Interactivity, interdisciplinarity, and accessibility to the general public are the three pillars of the project.
Five lectures exploring the challenges of AI
Each event will address a different social issue:
- October 1, 2026 – La Nef
What if AI were your confidant?
Can you confide in a chatbot? What are the risks? - October 22, 2026 – PA02
What if AI were wrong?
How can we recognize errors in artificial intelligence and maintain our critical thinking? - November 19, 2026 – Caméo
What if AI were subjective? Is artificial intelligence
truly neutral, or does it perpetuate certain biases? - February 25, 2027 – Quai 22
What if AI stole your creations?
What challenges does generative AI pose in terms of copyright and intellectual property? - March 18, 2027 – TRAKK
What if AI knew you too well?
What happens to our personal data, and to what extent can AI learn to know us?
While Elisa De Coster and Aline Nardi coordinate the project, they emphasize that it is, above all, a collaborative effort. The lecture series is led by ten doctoral students from the PReCISE and CRIDS research centers: Elisa De Coster, Adélaïde Couplet, Jules Dejaeghere, Pierre Luycx, Pierre Poitier, Aline Nardi, Alix Gobert, Florian Jacques, Martin Rappe, Lionel Goffaux, and Olga Thiry. Together, they aim to help the general public better understand artificial intelligence, without demonizing it or presenting it as a miracle solution.
Research at NaDI-CeRCLe
Agenda
Public Defense of a Doctoral Dissertation in Computer Science - Guillaume Nguyen
Computer science
Artificial intelligence (AI)
3
2026
14:00
-
17:00
Université de Namur, Faculté d'informatique, auditoire I02 - rue Grandgagnage - 5000 Namur
Contact person
:
Nguyen Guillaume
Harmonizing Regulations and Source Code: A Symphony of Compliance
Abstract
The increasing regulatory pressure on Cyber-Physical Systems (CPS), particularly in Europe, has turned compliance into a critical yet complex challenge for industry stakeholders. Many of these CPS are often long-lived systems with legacy code and limited (or no) access to representative documentation. This poses a problem when these systems need to comply with newer regulatory frameworks. Indeed, current conformity assessment practices rely predominantly on documentation review and operational observations, while the analysis of software artifacts remains underutilized. This situation is compounded by a persistent communication gap between legal experts and engineers, and a lack of systematic traceability between high-level regulatory obligations and low-level technical implementations. Such a disconnect frequently results in inconsistencies detected late in the development process, increasing correction costs and delaying time-to-market. Furthermore, the growing complexity of regulations, such as the Medical Device Regulation (MDR), contributes to the perception that compliance hinders innovation.
Transitioning from theoretical frameworks to industrial implementation presents significant challenges. During this research, efforts to validate the approach in real-world production environments were hampered by restricted access to sensitive data and architectures, as well as the inherent risks of intrusive analysis in highly interconnected systems. Consequently, this thesis emphasizes a conceptual framework validated through modular prototypes and isolated CPS categories (e.g., medical devices), demonstrating the effectiveness of the proposed methods where full-scale production deployment is not yet feasible.
This thesis addresses these challenges by investigating how regulatory requirements can be transformed into structured, traceable, and partially automatable elements directly linked to software artifacts. The research adopts an industry-grounded exploratory approach structured around three main axes: (1) the formalization of regulatory requirements to bridge the semantic gap between legal and technical domains; (2) the extraction of system functionalities from source code using Large Language Models; and (3) a unified framework, supported by tool prototypes, to bridge the gap between expected system behavior and actual implementation through evidence-based assessment.
By combining regulatory analysis, software engineering, and AI-based methods, this work contributes to redefining compliance as a continuous, traceability-driven process. Ultimately, it aims to support a paradigm shift toward “compliant-by-design” systems, enabling earlier detection of discrepancies and better alignment between regulatory intent and technical implementation in complex CPS environments.
Jury
- Prof. Xavier Devroey - University of Namur, Belgium
- Prof. Anthony Cleve - University of Namur, Belgium
- Prof. Benoit Vanderose - University of Namur, Belgium
- Prof. Jun Yang, P. Eng - Concordia University, Montreal, Canada
- Prof. Fuyuki Ishikawa - NII, Japan
- Prof. Paolo Arcaini - NII, Japan
Public Defense of a Doctoral Dissertation in Computer Science - Tony Leclercq
Computer science
6
2026
15:00
-
18:00
Université de Namur, Faculté d'informatique, auditoire I02 - rue Grandgagnage - 5000 Namur
Designing UI/UX guidelines for web-based sales configurators
Mass customisation is today a major industrial paradigm, allowing the conciliation of mass production scale economies with the individual needs and preferences of customers. The web configurators are a central element of this approach, allowing users to personalise products or services directly online according to their preferences.
The literature on configuration technologies is huge. However, most resource studies focus on the reasoning side of the configurator (i.e., the backend), such as knowledge models, reasoning mechanisms, and constraint solving. The design of the user experience (UX) or the user interface (UI) is still less studied. Nevertheless, many studies show that the quality of the interface influences the configuration experience, user satisfaction, and the perceived value of the personalised product; moreover, some studies report the need to study them in greater depth.
To achieve this objective, a state-of-the-art review of web configurator design was first conducted to identify existing limitations and research gaps, followed by a second review focusing on the perceived values associated with web configurators. An introspection of 100 web configurators was then conducted to identify characteristics that may influence their UI/UX quality. In parallel, empirical studies involving both end-users and configurator designers were conducted to investigate users’ expectations and preferences and to examine whether these expectations are accurately understood by designers. A prototyping phase subsequently evaluated alternative design solutions, aiming to determine how users’ expectations can best be addressed within configurator interfaces and to identify the trade-offs that may be required in practice. Finally, after the design guidelines were developed, their effectiveness was evaluated through user studies, while their clarity, relevance, and applicability were assessed by configurator designers.
This research contributes to bridging the fields of configuration technologies and Human–Computer Interaction. It provides both a deeper understanding of the factors influencing user experience in web configurators and a comprehensive set of design guidelines that can be directly applied to develop more effective, more intuitive, and more user-centred web configurators.
The Jury
- Prof. Patrick Heymans - University of Namur, Belgium
- Prof. Florentin Rochet - University of Namur, Belgium
- Prof. Bruno Dumas - University of Namur, Belgium
- Prof. Tomi Männistö - University of Helsinki, Finland
- Prof. Jean Vanderdonckt - UCLouvain, Belgium
- Prof. Deepak Dhungana - IMC – University of Applied Sciences, Austria

